Dashboard Alerts and Work Orders: Drill-Down, Event Mapping and Verified Closure
Verify the metric and source first, then choose read-only investigation, a business-system handoff or a work-order response. For equipment alarms, preserve event identity and separate alarm recovery from task completion; handle duplicates, delayed updates and failed assignment before calling the workflow closed.
On this page7 sections
First verify the alert, not just the red number
An indicator can turn red because a business threshold was crossed. It can also turn red because an API is delayed, a field was mapped incorrectly, the reporting scope changed, or the latest records have not arrived. Before anyone acts, the dashboard should expose the metric definition, time window, last update, source system and alert rule.
If an order count differs between a dashboard and ERP, compare filters, permissions, deduplication and snapshot time before creating a response task. The dashboard, ERP and Excel reconciliation guide walks through the checks. Treat a data-quality warning and a real operational exception as separate paths: they have different owners and remedies.
Drill down to an object, evidence and an accountable system
"View details" is useful only when an aggregate can lead to records someone can verify. For every drillable metric, map its aggregation rule, breakdown dimensions, stable object ID, source system and available action. If the source provides totals but no traceable records, present the dashboard as an analysis view; do not promise investigation of an individual event.
Scroll the table horizontally to see all columns.
| What appears on screen | Context needed next | Who confirms it |
|---|---|---|
| Alerted metric | Metric version, threshold, reporting time, source and data-quality status. | Metric owner and data owner. |
| Object details | Stable ID for an order, device, site or project, plus the viewer's permitted scope. | Source-system and permissions owners. |
| Response task | Event ID, priority, assignee, action and receipt fields. | Business system and responder. |
| Outcome | Source and update time for accepted, in progress, resolved or closed status. | Task or work-order system and acceptance owner. |
In scenarios involving equipment control or safety interlocks, a dashboard's viewing or response link does not grant control rights. Actual commands must remain inside the authorized business and safety system.
Choose the lightest response path that fits the work
The right workflow depends on whether a person must complete an action after spotting the exception.
- Read-only drill-down: Useful for analysis and reporting. The dashboard shows clues and records; people continue with the existing offline process.
- Open the business system: Useful when a mature handling page already exists. Pass only the object ID and necessary filters; the destination must check login and permissions again.
- Create a task or work order: Useful when assignment, progress history and an acknowledgement are required. Agree on event deduplication, status mapping, retries and closure criteria before integrating.
Automatically raising a ticket for every anomaly is rarely a sensible starting point. Without a clear owner or response rule, automation creates noise. Prove the path with a small set of high-value events first.
Preserve permissions and event identity across systems
The dashboard should transfer business context, not a shortcut around authorization. Define a stable event or object ID, timestamp and time zone, source system, current status, location of the acknowledgement and failure-handling behavior. The destination must still verify that the current user may see the object or perform the action. The OWASP Authorization Cheat Sheet calls for authorization checks on every request.
Creating a work order or writing back a result also needs duplicate protection. When a network timeout leaves the outcome unknown, query the original event or task before retrying. A second click must not silently create a second work order. The HTTP semantics specification explains why a client cannot blindly retry a non-idempotent request. Confirm whether the API actually supports deduplication during integration.
Test one alert from detection through acknowledgement
Suppose a dashboard flags abnormal energy use for a device. The operator opens its details and checks the device ID, location, reporting time and source record. After confirming a business exception, the operator submits a task through an authorized entry point. The dashboard shows "Dispatched," then updates only when the business system returns acceptance and resolution status.
Use the same test sample for successful dispatch, insufficient permission, delayed source data, rejected tasks, network timeout, repeated clicks, and a closed task whose metric remains abnormal. Record the source and returned state at every step. The same method works for an order, project, site or customer lead; it is not tied to one industry.
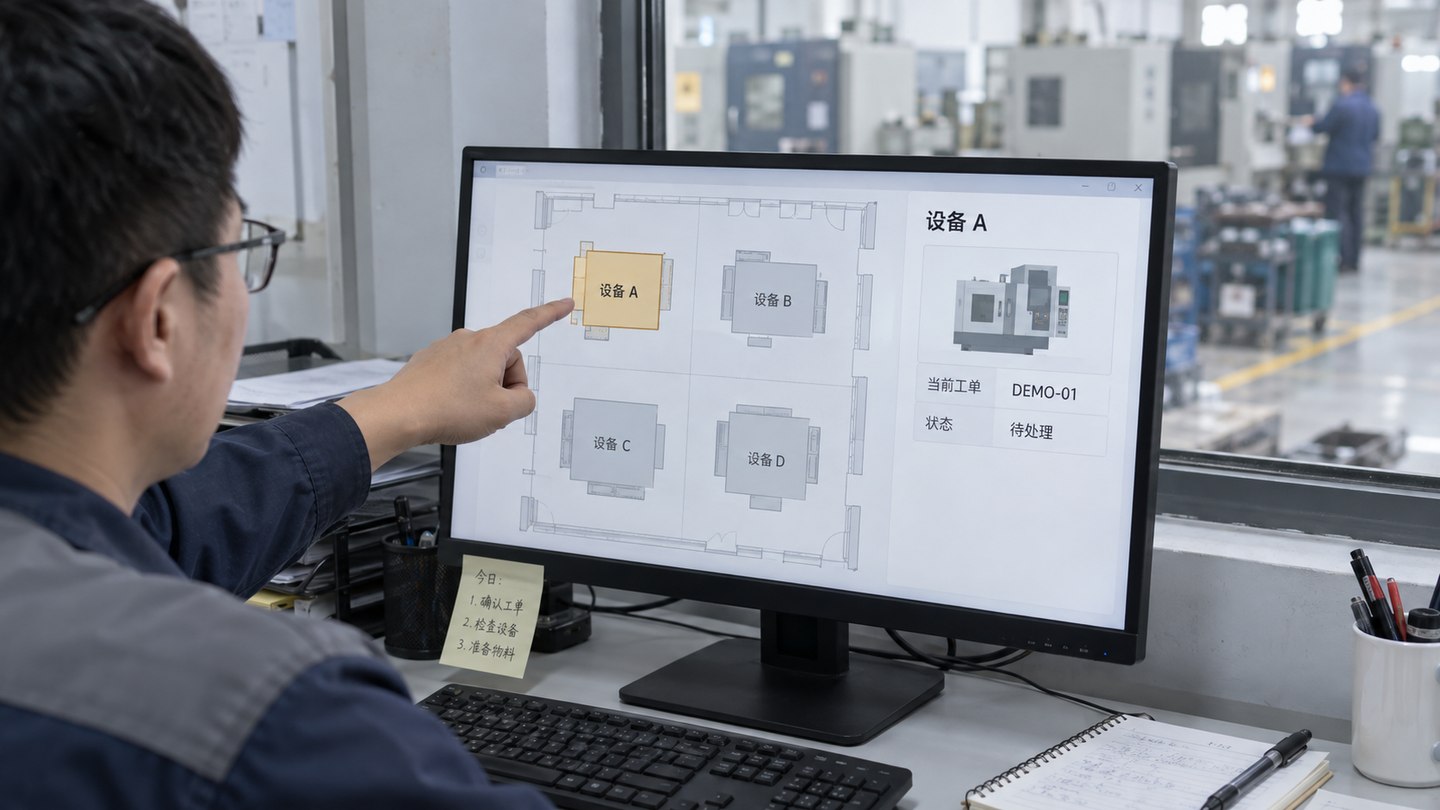
For a display-only project, stop at verified details. To create a response loop, confirm task ownership, permissions and status write-back against the software development scope (Chinese). For source integration, see enterprise dashboard data integration; for access and logging, see the dashboard permissions and audit checklist.
Map equipment alarms and work orders as separate state machines
An alarm describes a monitored condition; a work order describes the response to it. Return-to-normal does not prove that maintenance is complete, and closing a task does not establish that the monitored value has recovered. Keep the source alarm state and the task state independently visible, joined through an event-to-task relationship.
| Input or event | Work-order behavior to agree | Evidence retained |
|---|---|---|
| Repeated delivery of the same event | Return or update the existing task rather than creating another. | Stable source event ID, task ID and receipt/result. |
| Alarm returns to normal before acceptance | Record the recovery; retain or cancel the task only under the approved rule. | Recovery time, decision and accountable role. |
| Alarm reappears after recovery | Create a new event occurrence or reopen the appropriate task under an explicit rule. | Previous occurrence, new occurrence and linkage reason. |
| Work order closes while the alarm remains active | Show the unresolved discrepancy for review; do not overwrite the source state. | Closure reason, reviewer and current source state. |
| Response is lost after a create request | Query by the agreed idempotency/event key before resending. | Request key, query result and retry history. |
Use a source-system ID and an occurrence ID where the source supports them. If only a persistent alarm code is available, the integration must define what constitutes a new occurrence and how ordering is established. A device ID or alarm code alone cannot uniquely identify all events. A time-based merge window is a business rule, not a reliable replacement for event identity.
Test repetitions, out-of-order updates and changes of responsibility
- Provide one normal activation, acknowledgment, recovery and closure sequence. Compare the equipment event and task records side by side.
- Send the same creation event twice, including a timeout with unknown outcome. Confirm that the task count and mapping remain correct.
- Deliver a delayed activation after recovery and verify that a timestamp/version rule or reconciliation query prevents an obsolete state from replacing a newer one. Do not infer order only from message arrival.
- Test assignment failure, unavailable recipients, transferred responsibility and revoked access. Agree who reviews unassigned work rather than marking a notification as accepted.
- Close a task while its alarm is active, then reactivate an alarm after recovery. Verify both exceptions and the approved reopening/new-task rule.
Choose urgency, escalation and closure rules with maintenance staff. Only authorized people or systems should perform the applicable transition; a visible button or a successful login is not sufficient authorization. These are proposed integration checks, not a claim that every equipment or work-order product exposes all required events.
Bring alarm samples and the work-order API, including state definitions, event keys and failure responses, to scope software workflow integration (Chinese). For the upstream monitoring chain, see acquisition and platform responsibility boundaries.