How Should an Enterprise Data Dashboard Be Maintained After Launch?
Summary: After launch, maintenance covers more than data, metrics, accounts and servers. Define remote operations, on-site support, resident staffing, how SLA times are measured, disaster scenarios, backup and recovery, change rollback and service boundaries. Assign owners and keep verification records for critical items.
View the dashboard operations, SLA, disaster recovery and restoration checklist, or download the CSV.
Assign Maintenance Responsibilities First
An enterprise dashboard usually involves business teams, IT, data-source owners and the development or maintenance team. After launch, establish who owns each data source, account permissions, servers and page-content changes. Clear boundaries help locate a wrong number, unavailable page or metric change quickly.
1. Maintain Data Sources
Dashboard data can break when an API, spreadsheet, database or device platform changes. Name the owner of each source and API change, and retain field definitions, endpoint addresses, refresh intervals, test accounts and an exception-reporting method. Notify dashboard maintainers before a business-system upgrade so changed fields do not leave empty pages or wrong numbers.
2. Maintain Metric Definitions
Business growth may change how a metric is calculated. Does revenue include tax? Are cancelled orders counted? Is equipment availability measured by minute or hour? Record these definitions. For each change, log the date, reason and approver so departments do not interpret one number differently.
3. Maintain Page Content
Project names, images, descriptions, maps, equipment lists and presentation material may change. Provide a content-editing tool or a defined update process. Showroom, park and roadshow dashboards often change copy and images more often than metric logic; separating configurable content from code avoids a development cycle for every small update.
4. Maintain Accounts and Permissions
If the dashboard has an administration area or role-based access, periodically check active accounts, disable departed staff and protect administrator passwords. For pages containing operational, financial, customer or equipment data, verify that public-display permissions differ appropriately from internal-management permissions.
5. Maintain Servers, Certificates and Monitoring
For a server-hosted dashboard, monitor the domain, HTTPS certificate, firewall rules, system updates, CPU, memory, disk and logs. Expired certificates, full disks, service restarts and database connection failures can all make pages unavailable. Keep at least deployment instructions, service health checks, log locations, expiry dates, alert recipients and a troubleshooting record.
6. Plan Backups and Test Recovery
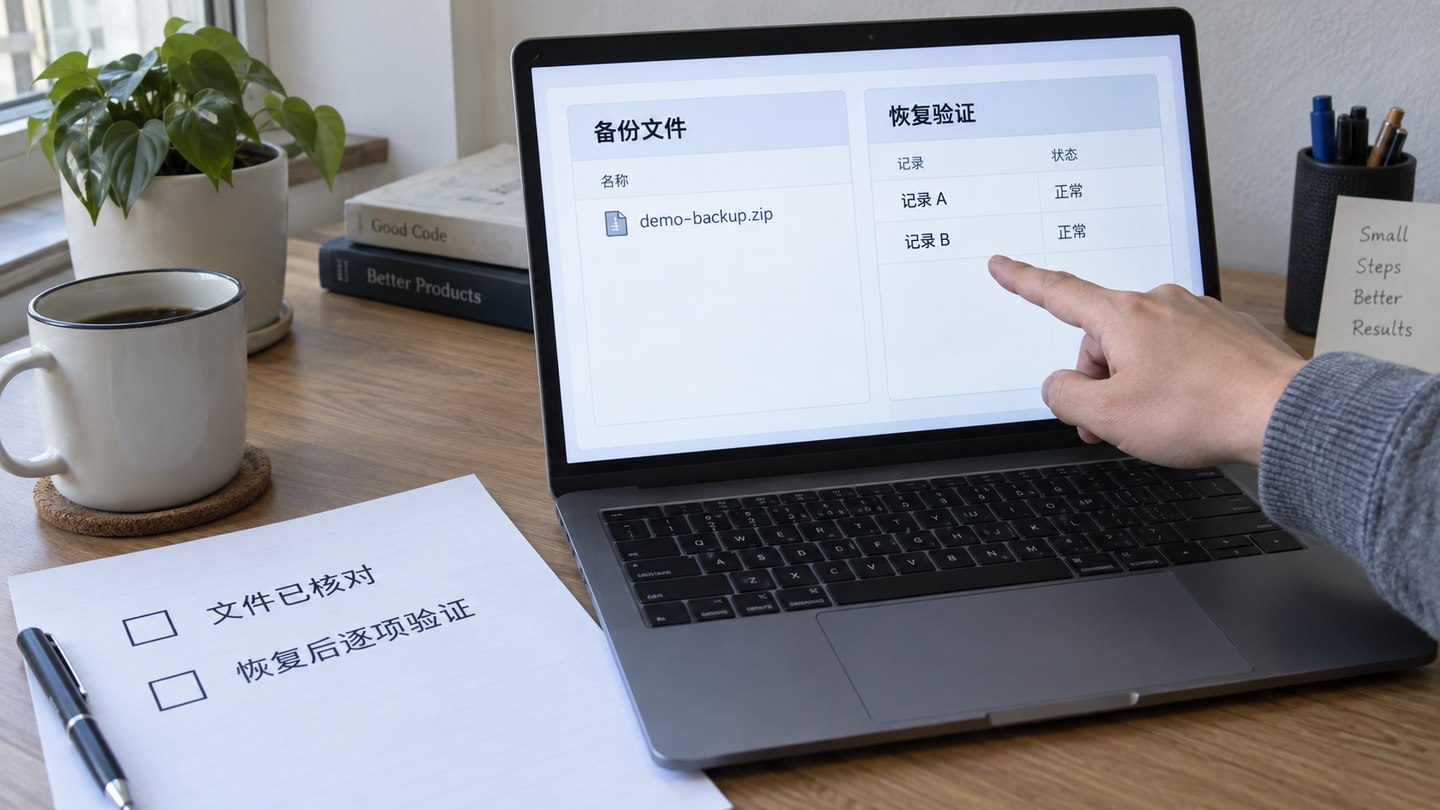
Backups may need more than the database: source code, release packages, configuration templates, database scripts, uploaded files, 3D models and scheduled-job settings may matter. After each backup, verify the job result, file size, storage location and failure alert. At an agreed interval, rehearse restoration in an environment where impact can be controlled; check the pages, accounts, critical data, APIs and scheduled jobs.
RPO is the maximum data-loss period the business can tolerate; RTO is the desired time to restore service after an incident. Set both from business impact, data update frequency and actual recovery capability, rather than copying numbers from another project.
7. Manage Changes, Rollbacks and Service Boundaries
Before a production release, record the change scope, test result, version, configuration differences, database scripts and rollback conditions. Check whether the last stable version can be restored. The maintenance agreement should distinguish defects, content edits, third-party changes and new requirements, and specify service hours, response channels, escalation contacts and exclusions.
8. Make the SLA Operational
An SLA needs more detail than “handle it quickly.” Define incident severity, affected scope, first-response time, treatment goal, escalation contact, communication channel and exclusions. A missing home page or core cockpit, a key metric that has stopped updating and a display issue on one low-priority page should not normally have the same response rule.
| Incident severity | Typical situation | What to confirm first |
|---|---|---|
| High impact | Core dashboard unavailable, all key data wrong, or page unusable before an important presentation. | Business impact, temporary display option, recovery goal, owner and escalation path. |
| Medium impact | Some metrics delayed, one module failing, or some accounts unable to log in. | Data-source state, recent changes, affected scope, estimated fix time and reviewer. |
| Low impact | Copy, image, style, noncritical filter or infrequently used page issue. | Whether it falls within maintenance, treatment batch, acceptance method and release window. |
Also state who owns third-party cloud services, networks, on-site hardware, browsers and devices, source systems and internal approvals. When domains, certificates, APIs, sources or accounts fail, teams can then follow the responsibility path instead of labeling every issue a “dashboard failure.”
9. Distinguish Remote Operations, On-Site Support and Resident Service
| Service model | Suitable work | Confirm before starting |
|---|---|---|
| Remote operations | Log investigation, configuration changes, API integration, version releases and user support. | Secure remote channel, account permissions, logs and permitted work window. |
| On-site support | Local network, display controller, hardware connections, closed networks or site-specific faults. | Dispatch conditions, entry approval, arrival time, travel costs and site contact. |
| Resident service | Ongoing attendance, inspection, coordination and incident handling at an agreed site and time. | Role, headcount, shifts, tools, work scope, replacement arrangements and fee. |
| Customer-run operations | Routine checks, account approval, business metric definitions, source coordination and content updates. | Training, documentation, permissions, escalation path and handover record. |
Remote operations are often efficient; on-site support needs access and scheduling; resident service is an ongoing staffing commitment and should not be assumed without a written scope. A 24/7 service promise is meaningful only when the service window, on-call method and incident levels are defined.
First response, restoration and final resolution are three different points in time. First response means the incident has been received and diagnosis has begun. Restoration means the core workflow or an alternative is available again. Final resolution means the root cause is fixed and verified. When travel or a third party is involved, record dispatch, journey, third-party handling and business sign-off separately.
10. Prepare Disaster Recovery and Temporary Display Options
Not every project needs a complex active-active architecture. An important cockpit should still identify scenarios such as server or database failure, object-storage faults, third-party map or API outages, network interruption, certificate expiry, stopped data feeds and faulty releases. For each, define detection, impact assessment, recovery steps and a business notification template.
Showrooms, presentations and command centers can also prepare a recent static snapshot, backup page, offline demo package or read-only summary report. A temporary display does not replace restoration, but it reduces presentation risk at a critical moment.
11. Continue Functional Iteration
Use real feedback after launch to improve charts, permissions, alarms, reports and administration. Classify requests as defects, blockers, experience improvements or future expansion, rather than mixing everything into one queue and losing control of maintenance time and cost. If teams rarely open the dashboard, follow the low-usage diagnostic path to check access, data trust and follow-up actions before deciding on a redesign.
Frequently Asked Questions
What if dashboard data stops updating after launch?
Check whether the source has new records, then inspect the API, database connection, scheduled jobs and front-end cache. Refreshing the page alone does not establish whether every step of the data pipeline is healthy.
Is a changed metric definition maintenance or a new requirement?
A field mapping or copy update may fit maintenance. A new source, rebuilt calculation or additional page module should be estimated as an iteration.
What information should the business retain?
Keep deployment instructions, API documentation, account inventory, metric definitions, page inventory, acceptance records, backup and recovery instructions, version history and maintenance contacts. Complete records make recovery, handover and future development easier.
If a backup succeeded, why rehearse recovery?
A successful backup only proves that a file or copy was created. It does not prove code, configuration, database and uploads can work together in the target environment. A rehearsal can reveal damaged backups, version mismatches, missing dependencies and incomplete steps.
Who should approve RPO and RTO?
The business owner should state tolerable data loss and downtime. The technical team then assesses backup frequency, storage, recovery steps and available resources. Record final targets in an agreement both sides can execute.
Can the same fixed SLA response time be promised for every project?
Not responsibly without considering the environment. Confirm the SLA against deployment, data-source ownership, service hours, severity, third-party dependencies and maintenance scope. Core outages, data errors and ordinary content edits need separate response rules.
How do remote operations, on-site support and resident service differ?
Remote operations cover logs, configuration, APIs and releases that can be handled over a secure connection. On-site support handles local network, displays, hardware and closed environments. Resident service assigns staff to work at a specified site and time. Agree separately on staffing, hours, arrival conditions, tools, travel and fees.
Are first response, restoration and final resolution the same SLA time?
No. First response means maintenance has received and started assessing the incident. Restoration means the core workflow or a fallback is usable. Final resolution means the root cause is fixed and verified. Track arrival, third-party handling and business confirmation separately.
Does disaster recovery always require two data centers or active-active systems?
No. Assess business impact, budget, recovery goals and on-site usage. Even without active-active systems, keep backups, recovery instructions, rehearsal records and any necessary temporary display option.
Related services: Data dashboard development.