How Does Custom AI + BI Executive Dashboard Development Differ from Off-the-Shelf BI?
An AI + BI executive dashboard cannot be accepted solely because its answers sound fluent. Check whether each question is authorized, whether metric definitions and query evidence can be traced, whether unauthorized requests are refused, and whether critical actions are logged. Final testing should use real role accounts, confirmed data, and a prepared question set. The model, database, and interface are only parts of the evidence chain.
Off-the-shelf software offers relatively fixed functionality and configuration boundaries. Custom development adapts data connections, metric semantics, permissions, interfaces, workflows, deployment, and deliverables to the client's current environment. A project can reuse suitable third-party components, but a product's defaults should not dictate the client's requirements.
Three direct answers about AI + BI projects
These address the choice of approach, preparation for kickoff, and pre-launch acceptance, subject in each case to validation in the actual environment.
What is the main difference between an AI + BI executive dashboard and off-the-shelf BI?
Off-the-shelf BI generally provides established data-modeling, analysis, and permission capabilities. A custom AI + BI project must also connect the client's existing metric meanings, data APIs, user roles, answer evidence, interface workflows, deployment environment, and deliverables. Neither approach is always preferable; choose based on current systems and acceptance responsibilities.
What should be prepared before starting an AI + BI project?
Prepare a set of real questions, a metric-definition table, data dictionary, role and data-scope matrix, traceable bases for answers, and categories of questions that require clarification or refusal. Select the model and interface after those inputs are clear, rather than treating a demo chat as the business scope.
How should natural-language data questions be accepted before launch?
Use real role accounts and a preapproved question set. Check answer accuracy, clarification of ambiguous requests, permission isolation, source traceability, no-answer handling, repeatability, and complete logs. Actions such as approval, price changes, payments, or customer intervention still require an authorized person to confirm them.
Project note: AI + BI capabilities must be validated against the client's actual data, permissions, and deployment environment. The final scope and acceptance criteria follow the project agreement. See the content notes (Chinese) for more detail.
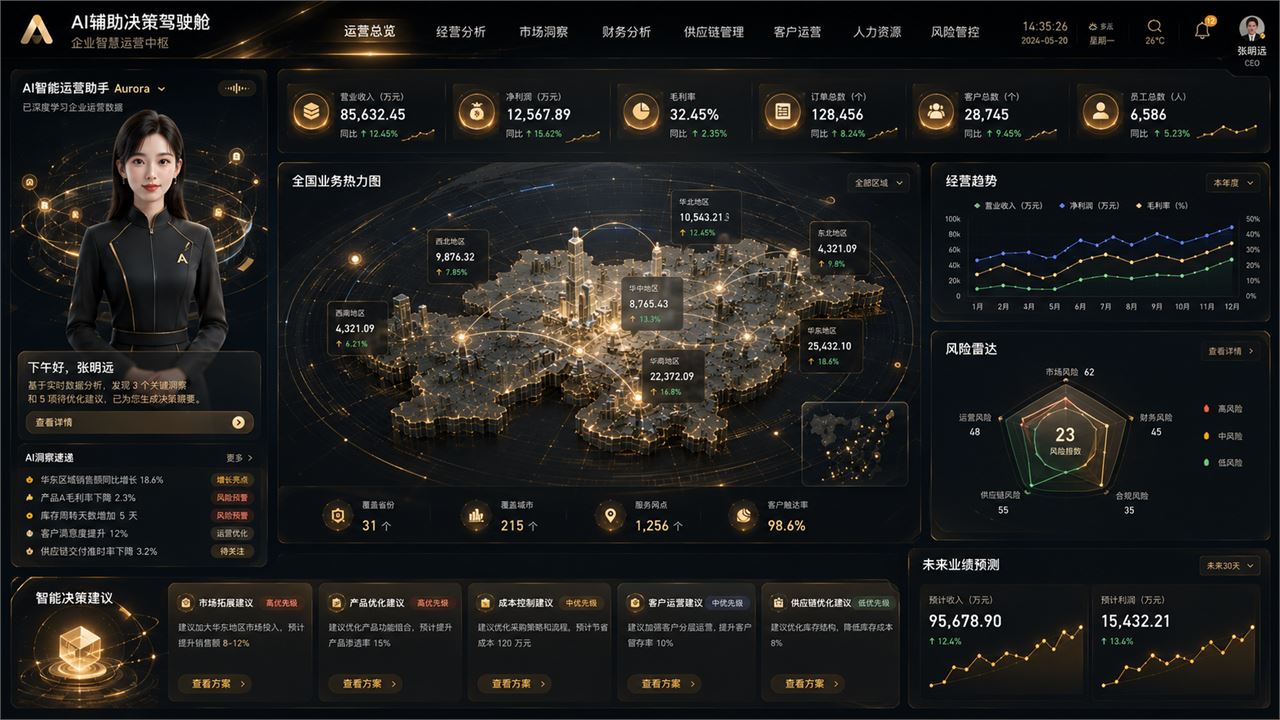
Illustrative AI-assisted decision dashboard. Names, metrics, and suggestions in the image explain information structure; they do not represent a real client, live operating data, or validated forecasts.
How custom AI + BI development differs from off-the-shelf BI software
Off-the-shelf BI is a closer fit when requirements are relatively standard, data sources fall within the product's supported range, organizational permissions map directly, and users accept its existing page and analysis conventions. Its common strengths are mature features, clear configuration paths, and quick activation of standard capabilities. The project must also accept its connectors, permission model, interface components, licensing, and upgrade approach.
Custom development is a closer fit when multiple business systems already exist, metric definitions cross systems, permissions must inherit the organization's identity structure, network deployment is restricted, or answers need to connect to work orders, approvals, alerts, and an executive dashboard. The point is not to rewrite every basic feature. Decide what to reuse, adapt, or build according to the actual APIs, data, permissions, and workflows.
Comparison dimension
Off-the-shelf BI software
Custom AI + BI development
Starting point
Select available capabilities from the product's modules and configuration options.
Work backward from the client's management questions, user roles, existing systems, and acceptance goals.
Data connection
Prefer databases, files, and standard connectors supported by the product.
Design adapters for existing databases, APIs, messages, file exchange, and specialized interfaces where required.
Metrics and semantics
Configure them within the product's data-model and metric modules.
Inherit and clarify the client's established definitions, historical versions, organizational scopes, synonyms, and cross-system lineage.
Identity and permissions
Use the product's roles, directories, and data-permission features.
Map centralized identity, organizational hierarchy, account policies, and data classifications to pages, APIs, rows, columns, exports, and sharing.
Deployment environment
Use topologies, versions, and dependencies supported by the product.
Determine deployment and integration around internal networks, private cloud, isolated zones, domestic hardware or software environments, gateways, and operations policies.
Interface and workflow
Rely mainly on the product's dashboards, components, and interactions.
Design dashboards, data questions, drill-down, alerts, and work-order or approval handoffs around each role, with separate authorization for business actions.
Delivery and acceptance
Focus on whether licensing, installation, configuration, and product features work.
Check agreed APIs, configuration, code or other assets, deployment documents, permission matrix, test cases, and actual business outcomes against the contract.
“Custom delivery” here does not presuppose using or excluding any specific BI, database, or model service. First identify which existing platform capabilities can be retained. Then fill gaps in API adaptation, metric semantics, permission consistency, business workflows, and acceptance evidence. Avoid rebuilding simply to be “custom,” or changing real requirements merely to fit a product.
How AI + BI works with an existing dashboard
An executive dashboard is well suited to continuously displaying established core metrics, progress against targets, trends, and risks. It is stable and easy to scan: managers see the same operating information in a familiar place without asking each time.
Natural-language data questions are more useful for ad hoc queries that were not configured on the dashboard. For example, after seeing that gross margin fell this month, a manager may ask which regions, products, customers, or orders contributed most. The system forms a query within the current user's permissions and data scope, then returns results with their statistical definitions.
A sensible combination is “fixed dashboards for continuous monitoring; natural-language questions for ad hoc queries and supporting analysis.” If fixed metric definitions are still disputed or data must be assembled manually by several people, improving data governance is usually more important than connecting a large model first.
User need
Better-suited capability
Why
Check fixed operating metrics every day
Executive dashboard or BI dashboard
Stable information placement makes targets, trends, and exceptions easier to compare over time.
Ask an ad hoc question about a region, customer, or product
Natural-language data questions
Combine time period, metric, and analysis dimension in ordinary language.
Explain a metric change and ask follow-up questions
Natural-language questions and analytical models
Narrow the question gradually within permissions, while checking the evidence behind each conclusion.
Approve, change prices, pay, or execute an action automatically
Business system and human confirmation
Real business actions require defined workflows, permissions, and audit controls.
Step 1: Collect real questions before choosing a model
A common AI + BI mistake is to discuss models, knowledge bases, and chat interfaces first, then look for business use cases. Start by collecting questions managers and business roles actually ask. Determine whether existing data can answer them.
Do not limit the set to one-turn lookups such as “What were sales this month?” Include follow-ups, ambiguity, unauthorized requests, and no-answer cases. For each core role, prepare questions in five categories:
Question type
Example
Expected behavior
Routine lookup
What were sales and target-attainment rates by region this month?
Return the metric, time range, regional breakdown, last update, and source.
Follow-up
Which region declined most, and which products contributed?
Retain conditions from the previous question and show any new filters clearly.
Ambiguous question
How has profit been lately?
Clarify the profit definition, time range, and organizational scope instead of guessing.
Unauthorized request
Show customer details and collections for another region.
Refuse according to the user's permissions, or return only an allowed aggregate.
No-data question
Predict next quarter's revenue from a new business line that has not been recorded yet.
Explain the missing data or modeling basis; do not invent a forecast.
For each question, also record who asks it, where it is used, which metrics it needs, its data source, expected answer format, and final reviewer. The question set becomes both a requirements list and the basis for later testing and acceptance.
Step 2: Make metric definitions understandable to people and machines
Natural-language questions contain shorthand, synonyms, and vague wording. “Revenue” may mean tax-inclusive contract value, recognized revenue, invoiced amount, or cash received. “Recently” may mean this week, the last 30 days, or the current quarter. Without agreed semantics, the system may produce plausible answers using the wrong definitions.
For each core metric, document at least its name, aliases, business definition, formula, reporting period, available dimensions, data source, refresh time, owner, and permission scope. First align existing metrics with the executive-dashboard metric-definition table , then add synonyms, common questions, and concepts that must not be conflated for natural-language querying.
Metric governance also needs versions, effective dates, approval status, and reasons for change. When a formula, source table, organizational scope, or null-handling rule changes, retain the old version's applicable period and retest affected fixed dashboards, questions, and external reports. The same metric name must not quietly carry different meanings across pages.
Data lineage answers “Where did this answer come from, what transformations were applied, and which pages depend on it?” Record upstream systems, tables, and fields, essential cleaning or aggregation rules, and downstream dashboards, reports, and natural-language entry points. Lineage need not cover every dataset at first, but core metrics must be traceable to verifiable sources.
During integration and launch acceptance, use the metric-definition and data-lineage acceptance matrix (Chinese) to track definition versions, effective dates, approvals, upstream and downstream lineage, dashboards that use each metric, permission level, and acceptance evidence. This keeps draft definitions from drifting away from production.
When a question has several reasonable interpretations, ask the user to choose. For “Why did sales decline?” establish whether sales means orders, invoices, or recognized revenue, and whether the comparison is year over year, period over period, or against target.
Test Text-to-SQL against the semantic layer and data dictionary; generating SQL is only one part of acceptance. Specify business terms, field names, table relationships, enumeration values, metric definitions, available dimensions, and disallowed combinations. The system needs to know which queries can run, which require clarification, and which must be rejected because of definitions or permissions.
Semantic-layer object
What to document
How to check at acceptance
Metric
Name, aliases, formula, reporting period, null handling, and owner.
Compare the same question with an approved report or confirmed SQL, item by item.
Metric version
Version number, effective date, approval status, reason for change, and replacement relationship.
Use the version applicable on the test date and rerun affected questions and reports.
Dimension
Organization, region, customer, project, product, time, and other available dimensions.
Check that drill-down, aggregation, and filtering stay within authorized scope.
Synonyms
Business abbreviations, common wording, easily confused concepts, and mappings that must not be used.
Test equivalent, ambiguous, and incorrect aliases for clarification and correct mapping.
Fields and table relationships
Data dictionary, primary and foreign keys, enumerations, refresh rate, and data-quality notes.
Retain generated SQL or the query plan; confirm joins and predicates are correct.
Data lineage
Upstream systems, tables, fields, transformation rules, and downstream reports and query entry points.
Trace an answer to its source and identify downstream effects after a change.
Disallowed combinations
Queries that cross organizations, tenants, sensitive fields, or incompatible definitions.
Use negative tests to check whether the system clarifies or refuses.
Step 3: Give AI access only to authorized data
Do not hand a highly privileged production database account directly to the model. A model interpreting questions should not gain the ability to bypass business permissions and query all data. Route queries through a controlled semantic model, read-only data service, or query layer. If MCP or another tool protocol is used, limit discoverable, callable, and returned capabilities to those approved for the current role.
The core permission test is that the same user can access only the same authorized data scope through fixed dashboards, natural-language questions, detail drill-down, export, and multi-turn follow-up. Removing sensitive words after an answer is generated cannot repair an unauthorized query.
Control point
What to confirm
Account and identity
Who asks the question, which organization and role they belong to, and whether the session is valid.
Data permissions
Which regions, departments, customers, projects, metrics, and detail levels may be viewed.
Whether personal details, contact information, financial records, and customer information must be masked or withheld.
Export and sharing
Whether answers, charts, and details can be exported, and whether shared results remain subject to permissions.
Audit records
Record the questioner, question, parsed conditions, data accessed, result status, and human corrections.
Permissions must be enforced before a query runs, not merely by deleting sensitive words from the final answer. For operating, financial, customer, or personnel data, also check whether fixed screens, office computers, mobile devices, and exported files honor the same display boundary. The dashboard permissions, security, and audit checklist can be used alongside this review.
Permission inheritance must reach topics, rows, columns, and operations
Access to the natural-language query entry point does not grant access to every dataset. Inherit roles from the organization's identity and hierarchy first, then restrict available workspaces or topics, datasets, row-level organizational scope, column-level sensitive fields, and export or sharing actions. Keep new topics, data sources, and roles closed by default until explicitly authorized.
A custom project should not assume one product's permission model. Inventory the client's centralized identity, AD, LDAP, single sign-on, organization tree, account lifecycle, and data-classification policies. Then decide whether to inherit directly, synchronize through APIs, use controlled data views, or add a separate permission adapter. Whichever method is chosen, verify consistent boundaries across pages, APIs, details, exports, and sharing with real role accounts.
Separate read-only queries from business actions in MCP or other tools
MCP can standardize tool discovery and calls, but does not automatically make a database, API, or business system read-only. Expose a separate query tool for data questions, using a restricted service account, read-only view, or read-only API. On the server, validate identity, tool authorization, parameters, data scope, and results. Do not mix modification, deletion, payment, approval, or notification into an ordinary query tool.
Control layer
Minimum requirement
Acceptance evidence
Tool catalog
Each role can discover only approved tools. Keep query and write operations separate, with new tools denied by default.
Tool lists for different roles, permission configurations, and version records.
Identity and authorization
Bind tokens or sessions to the target service, user, role, and minimum scope; do not forward privileged upstream credentials to downstream tools.
Authorized scopes, server-side validation logs, and regression tests for disabled accounts or revoked access.
Read-only execution
Service accounts, database views, API methods, and tool implementations must lack write privileges; limit datasets, rows, timeouts, concurrency, and frequency.
Database or API permission evidence, negative write tests, timeout results, and rate-limit results.
Inputs and outputs
Validate tool parameters, filter unauthorized fields, mask sensitive results, and prevent error messages from leaking structure or credentials.
Tests for unauthorized parameters, paraphrased requests, sensitive fields, error responses, and exports.
Query audit
Link the question, tool call, permission decision, query, and answer evidence with one interaction ID.
Tool name, parameter summary, data version, result scope, refusal reason, and human review record.
High-risk actions
Require separate authorization, display the pending action, obtain human confirmation, and provide reversal or remediation paths.
Confirmation UI, operation logs, refusal cases, and rollback results.
Work backward from the existing environment to choose deployment and integration
The same question-answering feature may require very different model calls, database connections, identity authentication, log collection, and operations in an internet-connected environment, internal network, private cloud, isolated network, or domestic hardware and software stack. First confirm network zones, available APIs, concurrency and timeliness, dependencies, backups and recovery, and upgrade ownership. Then choose a combination of local models, controlled external models, embedded BI, or an independent query service. Do not copy a product's default deployment path into the client's solution.
Validate field masking both in queries and results
Field type
Suggested handling
Negative test
Direct identifiers
Keep them out of the query dataset unless there is a business need; if needed, hide or partially mask them by role, or return aggregates only.
Try synonyms, detailed follow-ups, and exports to confirm column permissions cannot be bypassed to reveal original values.
Financial and operating details
Restrict rows and detail levels by organization, project, customer, or data classification.
Change region names, customer names, time filters, and sort order; confirm every result remains within the same scope.
Model prompts and system fields
Exclude tokens, connection strings, internal prompts, system tables, and audit fields from queryable data.
Ask directly for configuration, schema, or credentials; confirm refusal and a recorded permission decision.
Public aggregate metrics
Define aggregation level, minimum return scope, and rules for small samples.
Drill down repeatedly toward smaller organizations or individuals, checking for clarification or refusal at the boundary.
Classify questions as answerable, needing clarification, or requiring refusal
An answerable question needs all three conditions: authorized data, a clear metric definition, and an executable query. Clarify if time, organization, metric, or comparison is unclear. Refuse unauthorized details, sensitive fields, system configuration, or conclusions without a data basis. Creating work orders, sending notifications, changing prices, or approving requests are not ordinary data questions; they need a separate workflow and human confirmation.
Test unauthorized access through paraphrases, multi-turn conversation, exports, and permission changes
Prepare identical questions for administrators, department managers, regular staff, and fixed-display accounts, then compare the permitted result scopes.
Rephrase the same unauthorized request using abbreviations, synonyms, negation, and “only show an aggregate” to check that the rules cannot be bypassed.
Start with an authorized question, then switch to another region, customer, or person in a follow-up. Confirm that prior context does not expand permissions.
Check answers, charts, detail drill-down, image exports, data exports, and shared links separately, ensuring no exit path has broader permissions.
After revoking a role or data permission, sign in again and start a new session. Check whether caches, conversation history, or old sharing links still expose data.
Test messages for insufficient permissions, no data, timeouts, and API failures. The system should describe the true state instead of generating a substitute answer.
Logs should reconstruct what happened in a data-question interaction
Use one interaction ID to connect the question, permission decision, query execution, and returned answer. At a minimum, record user and role, analysis topic or data source, recognized metrics and filters, permission decision, query status, result scope, data or metric version, time taken, refusal reason, and human corrections. Decide whether to retain full SQL, the original question, and result details according to sensitivity, troubleshooting needs, and retention policy. Avoid logging passwords, tokens, or unnecessary personal information.
Step 4: Attach a verifiable basis to every answer
A particularly dangerous result in business analysis is an answer that looks right but hides how it was calculated. Natural-language data results should return more than a sentence or chart; they should include enough information for verification.
A verifiable answer should identify at least the metric, reporting period, filters, analysis dimensions, data source, last update, and permission scope. When explaining an exception, distinguish facts shown directly by the data from possible causes inferred by rules or models.
For example, the system can establish “This month's gross margin in North China is lower than last month's” as a calculated result. “Mainly because competitors cut prices” is only a hypothesis requiring verification unless supported by external data; it must not be stated as a confirmed cause.
For important management conclusions, retain query conditions, a result snapshot, or a link to the corresponding report so the business owner can check original data. If metric definitions conflict, data is stale, or a result is abnormal, show a warning and make uncertainty explicit.
Answer type
Required basis
How the system should express it
Acceptance and retained evidence
Metric fact
Approved metric version, time range, filters, permissions, and source data
Return the result with its definition, scope, source, and last update
Compare with an approved report or SQL and retain the question, conditions, and result snapshot
Rule- or model-based judgment
Identifiable rule, features, model, or knowledge source and version
Label it clearly as analysis, classification, or inference, not raw fact
Retain versions, input scope, output, and human review outcome
External business cause
External data or official records that can be accessed with authorization and verified
When evidence is insufficient, list it as an unverified hypothesis rather than confirming causation
Record missing evidence and who will verify it
Sensitive information or business action
Role authorization, workflow rules, reviewer role, and action-confirmation process
Refuse unauthorized requests; for price changes, payment, or approvals, provide reference information and route to a controlled process
Test refusal, human confirmation, reversal paths, and audit logs
Step 5: Define what AI may recommend and what decisions remain human
AI can help managers look up numbers, summarize and compare results, flag exceptions, and suggest analysis paths. It should not automatically replace the authorized business owner making a final judgment.
For price changes, payments, credit decisions, customer actions, personnel evaluations, procurement, and approvals, treat AI output as reference material. An identified role should review it and confirm the action in the business system. If a project wants to move from “detect a problem” to “create a work order, send a notification, or execute an operation,” separately design workflow permissions, confirmation steps, reversal methods, and audit records.
Project documentation should also list questions that must not be answered: details outside the authorized scope, forecasts without a data basis, comparisons involving sensitive personal information, and management recommendations whose sources cannot be explained. Refusal and clarification are normal states in a trustworthy system.
Step 6: Accept natural-language data questions with a question set
AI + BI acceptance must cover accuracy, repeatability, and permission isolation. “The chat returned something” is only a starting point. Under fixed data and metric definitions, the same question should be verifiable again. When different roles ask it, their result scopes must be checked too.
Acceptance dimension
Test method
Passing behavior
Metric accuracy
Compare standard questions against approved reports item by item
Metrics, formulas, time periods, filters, and aggregation methods agree.
Metric versions
Replay a question under different effective dates
The applicable version is used, and the answer can identify the definition version and change date.
Synonyms and ambiguity
Enter abbreviations, old names, near-synonyms, and vague terms
Map correctly or ask for clarification; do not choose a definition without authorization.
Multi-turn context
Change region, time period, and analysis dimensions across follow-ups
Retain valid conditions and show every change in conditions clearly.
Permission isolation
Ask the same question as different roles
Answer scopes match role permissions; unauthorized requests are refused and logged.
Sources and lineage
Trace an answer through metrics, fields, transformations, and downstream pages
Business users can verify it against data or reports, and the impact of changes can be identified.
Failure handling
Simulate no data, API failure, timeout, and unsupported questions
Explain the real condition; never fabricate a result.
Human correction
Correct a synonym, metric mapping, or wrong answer
An owner, record, and retest procedure are defined.
Operations records
Sample query, permission, and exception logs
Critical behavior is traceable and sensitive content is retained only under policy.
Set response-time, concurrency, and availability targets according to data volume, query complexity, deployment environment, and business timeliness. Do not copy one numerical target from another project. An acceptance report should record passing and failing questions, limitations, and improvements still needed.
Pilot with one role and one business domain
An initial project need not cover every department and all operating data. Choose a frequently used setting with relatively stable metrics and clear permissions, such as sales review, project progress, collections analysis, or inventory exceptions.
The pilot should include a fixed dashboard, natural-language entry point, standard question set, user roles, answer evidence, and a human reviewer. Afterward, ask whether staff actually pose questions, whether answers are verifiable, where failures cluster, and how much ongoing work is needed to maintain metric meanings and the question set.
If the main need is a fixed report and the existing dashboard already meets it, or business data still has to be assembled from offline spreadsheets with conflicting metric definitions, the first phase can improve the dashboard and data governance instead of adding AI complexity for its own sake.
What the client and implementation team each own
Role
Main responsibility
Business owner
Confirm real questions, metric meanings, intended use, business boundaries, and final decision responsibility.
Data owner
Confirm sources, quality, refresh times, exception handling, and traceability.
Security and system administrator
Confirm identity, permissions, masking, logs, deployment, and account-management requirements.
Implementation team
Build question parsing, semantic mapping, query controls, result presentation, tests, and documentation.
Acceptance reviewer
Independently check results with a standard question set and accounts with different permissions, not just a demo.
After launch, assign owners for metric aliases, example questions, data mappings, permissions, and error feedback. When metrics, organizational structures, data sources, or frequent questions change, update and retest natural-language querying too.
Basis and applicability boundaries of the custom approach
This method follows the requirements, design, integration, and acceptance path common in custom projects: understand existing systems and management questions; define metrics, APIs, permissions, deployment, and delivery boundaries; and finally run regression tests with real accounts, data, and questions. It is not a manual for one BI product and does not promise that any ready-made component can meet project needs without adaptation.
For data-quality dimensions, refer to GB/T 25000.12-2017 Data Quality Model in China's public national-standards catalog. For permissions and logs, see the OWASP Authorization Cheat Sheet and OWASP Logging Cheat Sheet. For AI risk identification, roles, and ongoing governance, see the NIST AI Risk Management Framework. For MCP integration boundaries, review MCP Authorization and MCP Tools. Product examples of row and column permissions and semantic modeling include SQLBot permission settings and Quick BI basic concepts. These sources add review dimensions; they are not product certification or automatic compliance conclusions. The actual architecture, applicable requirements, and acceptance criteria still depend on the client's policies, deployment environment, contract, and professional assessment.
Frequently asked questions
What is the difference between custom AI + BI development and off-the-shelf BI?
Off-the-shelf BI is normally configured around existing product features, connectors, permission models, and deployment methods. Custom development starts from the client's workflows, data systems, metric definitions, identity permissions, deployment network, and acceptance requirements. “Custom” does not mean building everything from scratch: suitable database, model, BI, and identity components can be reused, but project requirements determine data adaptation, semantics, permissions, interfaces, workflows, and delivery boundaries.
Does custom development mean building every capability from scratch?
No. A project can retain or integrate databases, data platforms, BI, model services, and identity systems that meet requirements, then focus custom work on existing-system connections, metric semantics, permission mapping, business processes, interface interactions, and acceptance evidence. Choose procurement, embedding, or development according to API openness, licensing boundaries, deployment conditions, and long-term ownership.
Can we try natural-language data questions before our enterprise data is complete?
A limited pilot in one relatively stable business domain is possible, but first define core metrics, sources, refresh schedules, permissions, and owners. When data definitions remain in conflict, natural-language queries expose the problem sooner; they do not replace data governance.
Can a large model connect directly to the production database?
Do not hand a highly privileged database account directly to the model in production. Prefer read-only data services, a controlled semantic model, or MCP and tool services that expose only query capabilities. Enforce account permissions, query allowlists, row and column rules, masking, timeouts, and audit logs on the server. Calling a tool “read-only” does not replace those controls.
How do we keep natural-language answers from using the wrong metrics?
First align metric names, formulas, time definitions, dimensions, and synonyms. Show the reporting period, filters, source, and last update with each answer. If a question is ambiguous, no data exists, or permissions are insufficient, clarify or refuse explicitly rather than guessing.
Is correct Text-to-SQL output enough to launch natural-language querying?
No. Also test question parsing, semantic mapping, permission filters, SQL execution scope, result interpretation, answer evidence, and audit logs. Even correct SQL should fail acceptance if the metric definition, permission decision, or explanation is wrong.
What matters most in AI + BI acceptance?
Test accuracy on standard questions and multi-turn follow-ups, clarification of ambiguity, permission isolation, source traceability, no-answer handling, response consistency, logging, and human correction. A chat box that returns text is only the foundation.
Can AI make management decisions directly for executives?
That is not recommended. AI can help query, summarize, explain, and flag risks, but an authorized business owner should review operating decisions in light of data quality, business context, and external factors. Actions such as approvals, price changes, payments, or customer interventions still need human confirmation.